

Introducing Health Monitoring
Ghostwriter monitors the health of its services in two ways: Docker health checks and internal monitoring and testing.Docker Health Checks
Docker automatically monitors the containers viaHEALTHCHECK commands (see Docker documentation for technical information). These commands check to make sure the service is responding and basic functionality is working.
The results of these commands can be checked with this command:
0), the Status column will show healthy. Any other exit code will flip the status to unhealthy, indicating the service is likely not functioning properly.
By default, the commands run with these attributes that can be adjusted via Ghostwriter CLI’s config set command:
-
Start running after 30s (
HEALTHCHECK_START, default is30s) -
Run every 120s (
HEALTHCHECK_INTERVAL, default is120s) -
Timeout after 10s (
HEALTHCHECK_TIMEOUT, default is10s) -
Will be retried once (
HEALTHCHECK_RETRIES, default is1)
Internal Testing and Monitoring
Ghostwriter also tests each service more thoroughly with two API endpoints:- /status/
- /status/simple/
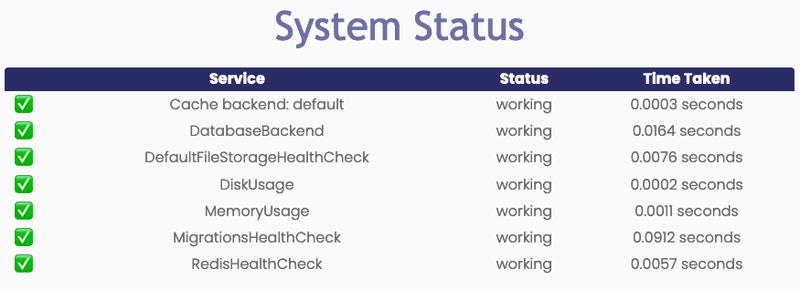
This endpoint also provides public machine-readable status if you set the
Accept: application/json header or request /status/?format=json. Authentication is not required. These responses contain only service names and basic values: working, warning, or error. Diagnostic messages and check configuration are limited to the privileged HTML page.Dashboard Monitoring
The home dashboard reads the latest background result from a single shared database record. It never runs diagnostic checks or queues monitoring work while loading, including when the record is missing or stale. There is no diagnostic loading delay for dashboard visitors. A Django Q schedule named Dashboard system health runs every minute and checks the cache, database, storage, disk, memory, Redis, and Hasura. The schedule is installed by the database migration and requires the queue service to be running. Each scheduled run has a 30-second worker timeout. Successful monitor runs are not saved in the background-job history. The queue scheduler restores this required schedule on its next tick if it is missing, including after database resets or deletion while the application is running. Existing names, intervals, and intentional pauses are preserved. To disable monitoring, pause the schedule by setting its repeats to zero. Missing schedules are restored with the default one-minute interval. The monitor skips missed intervals after downtime and runs one current check before scheduling its next future run. It does not replay historical checks, even when catch-up is enabled for other scheduled tasks. Results remain current for three minutes from the start of the checks. Missing results, incomplete checks, or older results display System status unavailable instead of claiming the services are ready. If the queue stops or falls behind, the dashboard continues loading and the summary becomes unavailable. Managers and admins can visit the detailed status page to run fresh checks independently; those checks do not replace the background snapshot. Every user sees the same compact health indicator: green for Systems ready, yellow for System warning, red for System error, and a neutral indicator for System status unavailable. Uncleared failed jobs also produce a warning indicator, without hiding current service errors or unavailable health results. Regular users receive guidance to contact a manager or admin when attention is needed. Diagnostic details and the View status link are limited to managers and admins. The indicator never blocks normal navigation or editing. Changes in service health normally appear after the next background run; detection may take longer if the queue is busy. Failed-job notifications are queried separately on each dashboard load, so clearing them takes effect immediately. Clearing notifications preserves task history and does not clear current service warnings.Configuration
The dashboard services map to the following configuration variables:-
DiskUsage:
HEALTHCHECK_DISK_USAGE_MAX(Default is90[percentage]) -
MemoryUsage:
HEALTHCHECK_MEM_MIN(Default is100[in MB])
.env file or with Ghostwriter CLI (this sets and reads from .env). For changes in .env or using the CLI, bring containers down and up.
Example .env snippet with default values:
Automated Monitoring
You can automate monitoring with something like Uptime Kuma or a similar tool. The recommended logic is:- Request the /status/simple/ endpoint
- Check for the response code and content
-
If
OKis not in the response or the response code is not200, send an alert with a link to /status/ for details
working status. A service experiencing a problem reports only warning or error. JSON and text responses return HTTP 200 when all checks pass and 500 when a check warns or fails. Link alerts to /status/ so a manager or admin can sign in and inspect the diagnostic messages.
Public monitoring also supports format=text, format=atom, format=rss, and format=openmetrics, or the corresponding Accept headers. These formats omit raw errors and configured URLs, paths, and credentials. OpenMetrics retains the package’s metric names and check label values, but omits configuration labels. Feeds and OpenMetrics retain HTTP 200 when checks fail; their contents carry the health result.
Opening /status/ in a browser still requires an active manager or admin session. All machine-readable responses remain basic, including when requested by a privileged user.